Inter-transcriber Agreement (ITA)
The Inter-transcriber Agreement (ITA) analysis compares blind transcriptions on the IPA Actual tier against their shared IPA Target. It reports per-word agreement, pooled agreement, and Cohen's Kappa for all phones, consonants, and vowels. Every pair of transcribers is compared: with transcribers EY, SM, and JC the report scores EY vs SM, EY vs JC, and SM vs JC.
Use ITA for reliability studies in which two or more transcribers independently transcribe the same recordings using blind transcription.
Before you begin
Each record must have a non-empty IPA Target and at least two blind transcriptions on IPA Actual. Check target word division and syllabification, because the analysis selects and aligns results by target word.
ITA compares every pair of transcribers that have blind IPA Actual transcriptions
in the session. Transcribers are paired in the order they are listed in the session,
so within a pair T1 is the transcriber listed first. There is no
control for choosing a subset of pairs.
For every target word, Phon automatically aligns the target separately with each blind production. Inter-word pauses transcribed by only one transcriber do not shift this alignment. A word is scored for a pair only when both of its transcribers have a resolvable, non-empty production aligned with it; a word may therefore be scored for one pair and skipped for another.
See Blind Transcription for the transcription workflow.
Run the analysis
- Select the sessions containing the blind transcriptions.
- Choose .
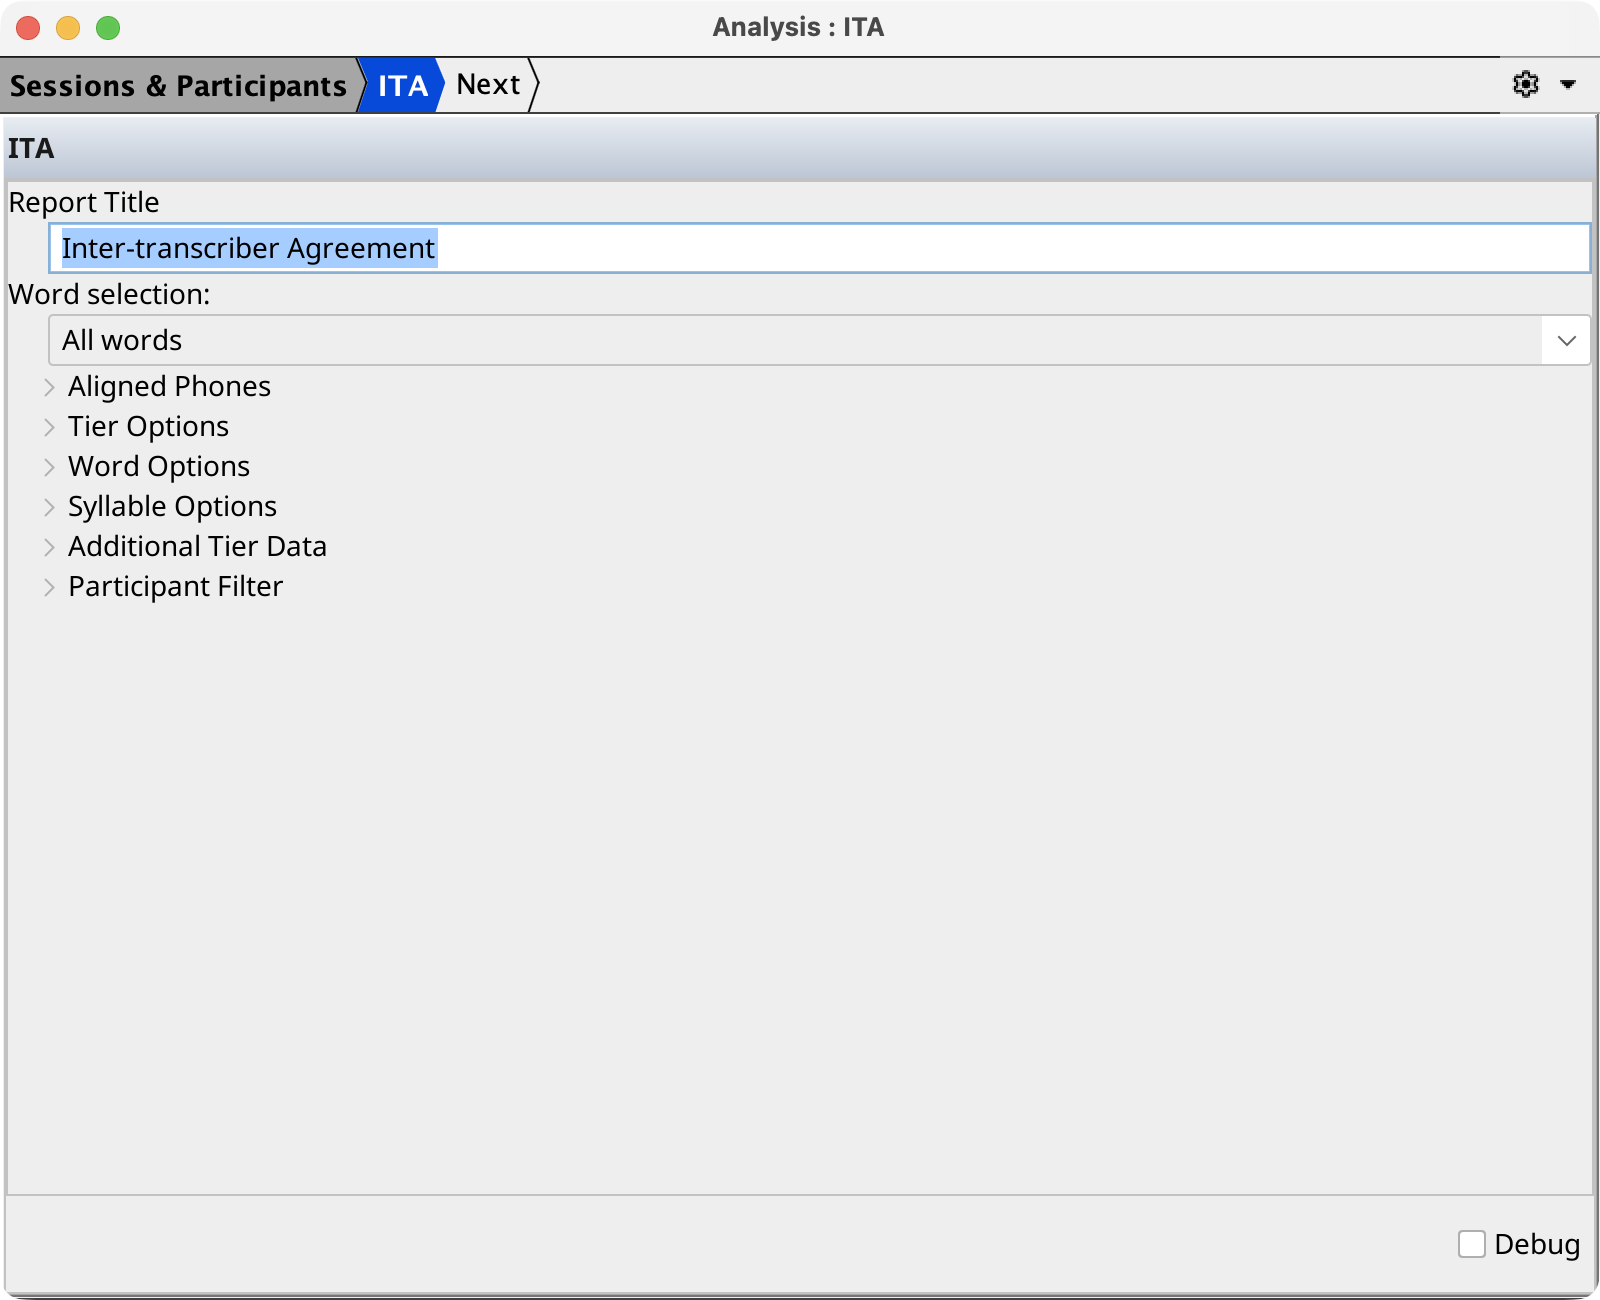
- Configure the ITA parameters and run the analysis.
| Parameter | Default | Effect |
|---|---|---|
| Report Title | Inter-transcriber Agreement | Sets the title of the generated report. |
| Word selection | All words | Selects all, monosyllabic, disyllabic, monosyllabic and disyllabic, or polysyllabic (three or more syllables) target words. Choosing a length preset also adds that selection to the default report title. |
| Aligned Phones | Empty IPA Target and IPA Actual Phonex matchers | Optionally restricts the aligned target/actual results used to find words for the analysis. |
| Tier, word, syllable, and participant options | No additional restriction | Applies the standard query filters before ITA scoring. |
| Additional Tier Data | Orthography aligned words | Adds Orthography to each result row. Other aligned tiers or words may also be selected. |
For the shared filtering controls, see Common Query Parameters and Aligned Phones.
How agreement is scored
For each audible target phone, each transcriber's aligned production is classified
as correct (C), substituted (S), or deleted
(D). ITA compares these outcome categories; it does not compare
the identity of two substituted phones.
| Column | Meaning |
|---|---|
Transcribers |
The pair being compared, for example EY vs
SM. |
T1, T2 |
The two blind IPA Actual words being compared, in pair order. |
A |
Target-phone positions where both transcribers received the same
outcome category. For example, two different substitutions still
count as agreement because both outcomes are
S. |
D |
Target-phone positions where the outcome categories differ. |
EA |
Epenthesis agreement: both transcribers inserted a phone at the same alignment position. The inserted phones do not have to be identical. |
ED |
Epenthesis disagreement: only one transcriber inserted a phone at that alignment position. |
AA, DD,
AD, DA |
The two-by-two contingency counts used for Kappa: both correct, neither correct, only T1 correct, and only T2 correct. Epenthesis is treated as disagreement with the target. |
ITA |
(A + EA) / (A + D + EA + ED). The result is 0
when there are no scored positions. |
κ |
Cohen's Kappa calculated from the
AA/DD/AD/DA contingency counts. |
Phone classes
The Consonants and Vowels tables filter target phones by their consonant or vowel feature. Glides are in neither class, so they appear only in the combined all-phone results.
An epenthetic phone is assigned to a class using the inserted phone. If both transcribers insert at the same position but the phones belong to different classes, T1's inserted phone determines the class.
Report output
The report contains a Summary table, one section per transcriber pair, and a Skipped table:
| Table | Contents |
|---|---|
| Summary | Pooled counts, ITA, and Kappa for every pair, with one row per pair and phone class (All Phones, Consonants, and Vowels), so pairs can be compared side by side. |
| Pair section, for example EY vs SM | Holds the three per-word tables below for that pair. |
| Consonants and Vowels | Per-word results over every audible target phone, followed by a
Total row. |
| Consonants | Per-word results restricted to target consonants, followed by a
Total row. |
| Vowels | Per-word results restricted to target vowels, followed by a
Total row. |
| Skipped | Unscored target words for each pair. Typical causes are a
transcriber who did not transcribe the record, a missing target, an
empty production for either transcriber, or a word that cannot be
aligned. The Transcribers column names the pair
(or the lone transcriber when a session has fewer than two), and the
T1 and T2 columns show whichever productions could be
resolved. |
Each Total row pools the counts across all scored words of its
pair. ITA and Kappa are recalculated from those pooled counts rather than averaged
from the per-word values.